01 / REAL-TIME SYSTEMSBeta
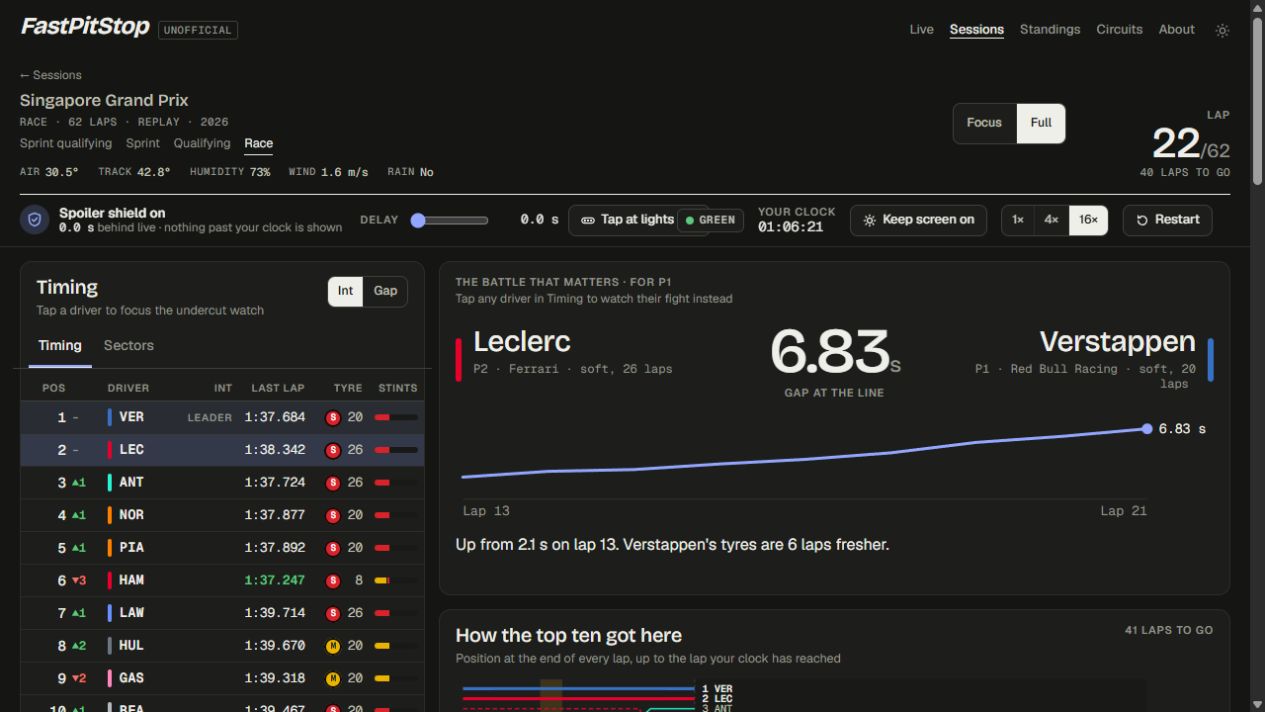
Race desk · live-site replay capture
FastPitStop
Race intelligence. Without the spoilers.
A second-screen race companion where timing, strategy, and AI explanations follow the viewer’s clock.
I build systems.
I study how they think.
From AI agents to the bytes inside a model. A collection of things I’ve built, experiments I’ve designed, and questions I’m still chasing.
Step inside the workStep into the interfaces, look under the hood, and see where the evidence ends.
Race intelligence. Without the spoilers.
A second-screen race companion where timing, strategy, and AI explanations follow the viewer’s clock.
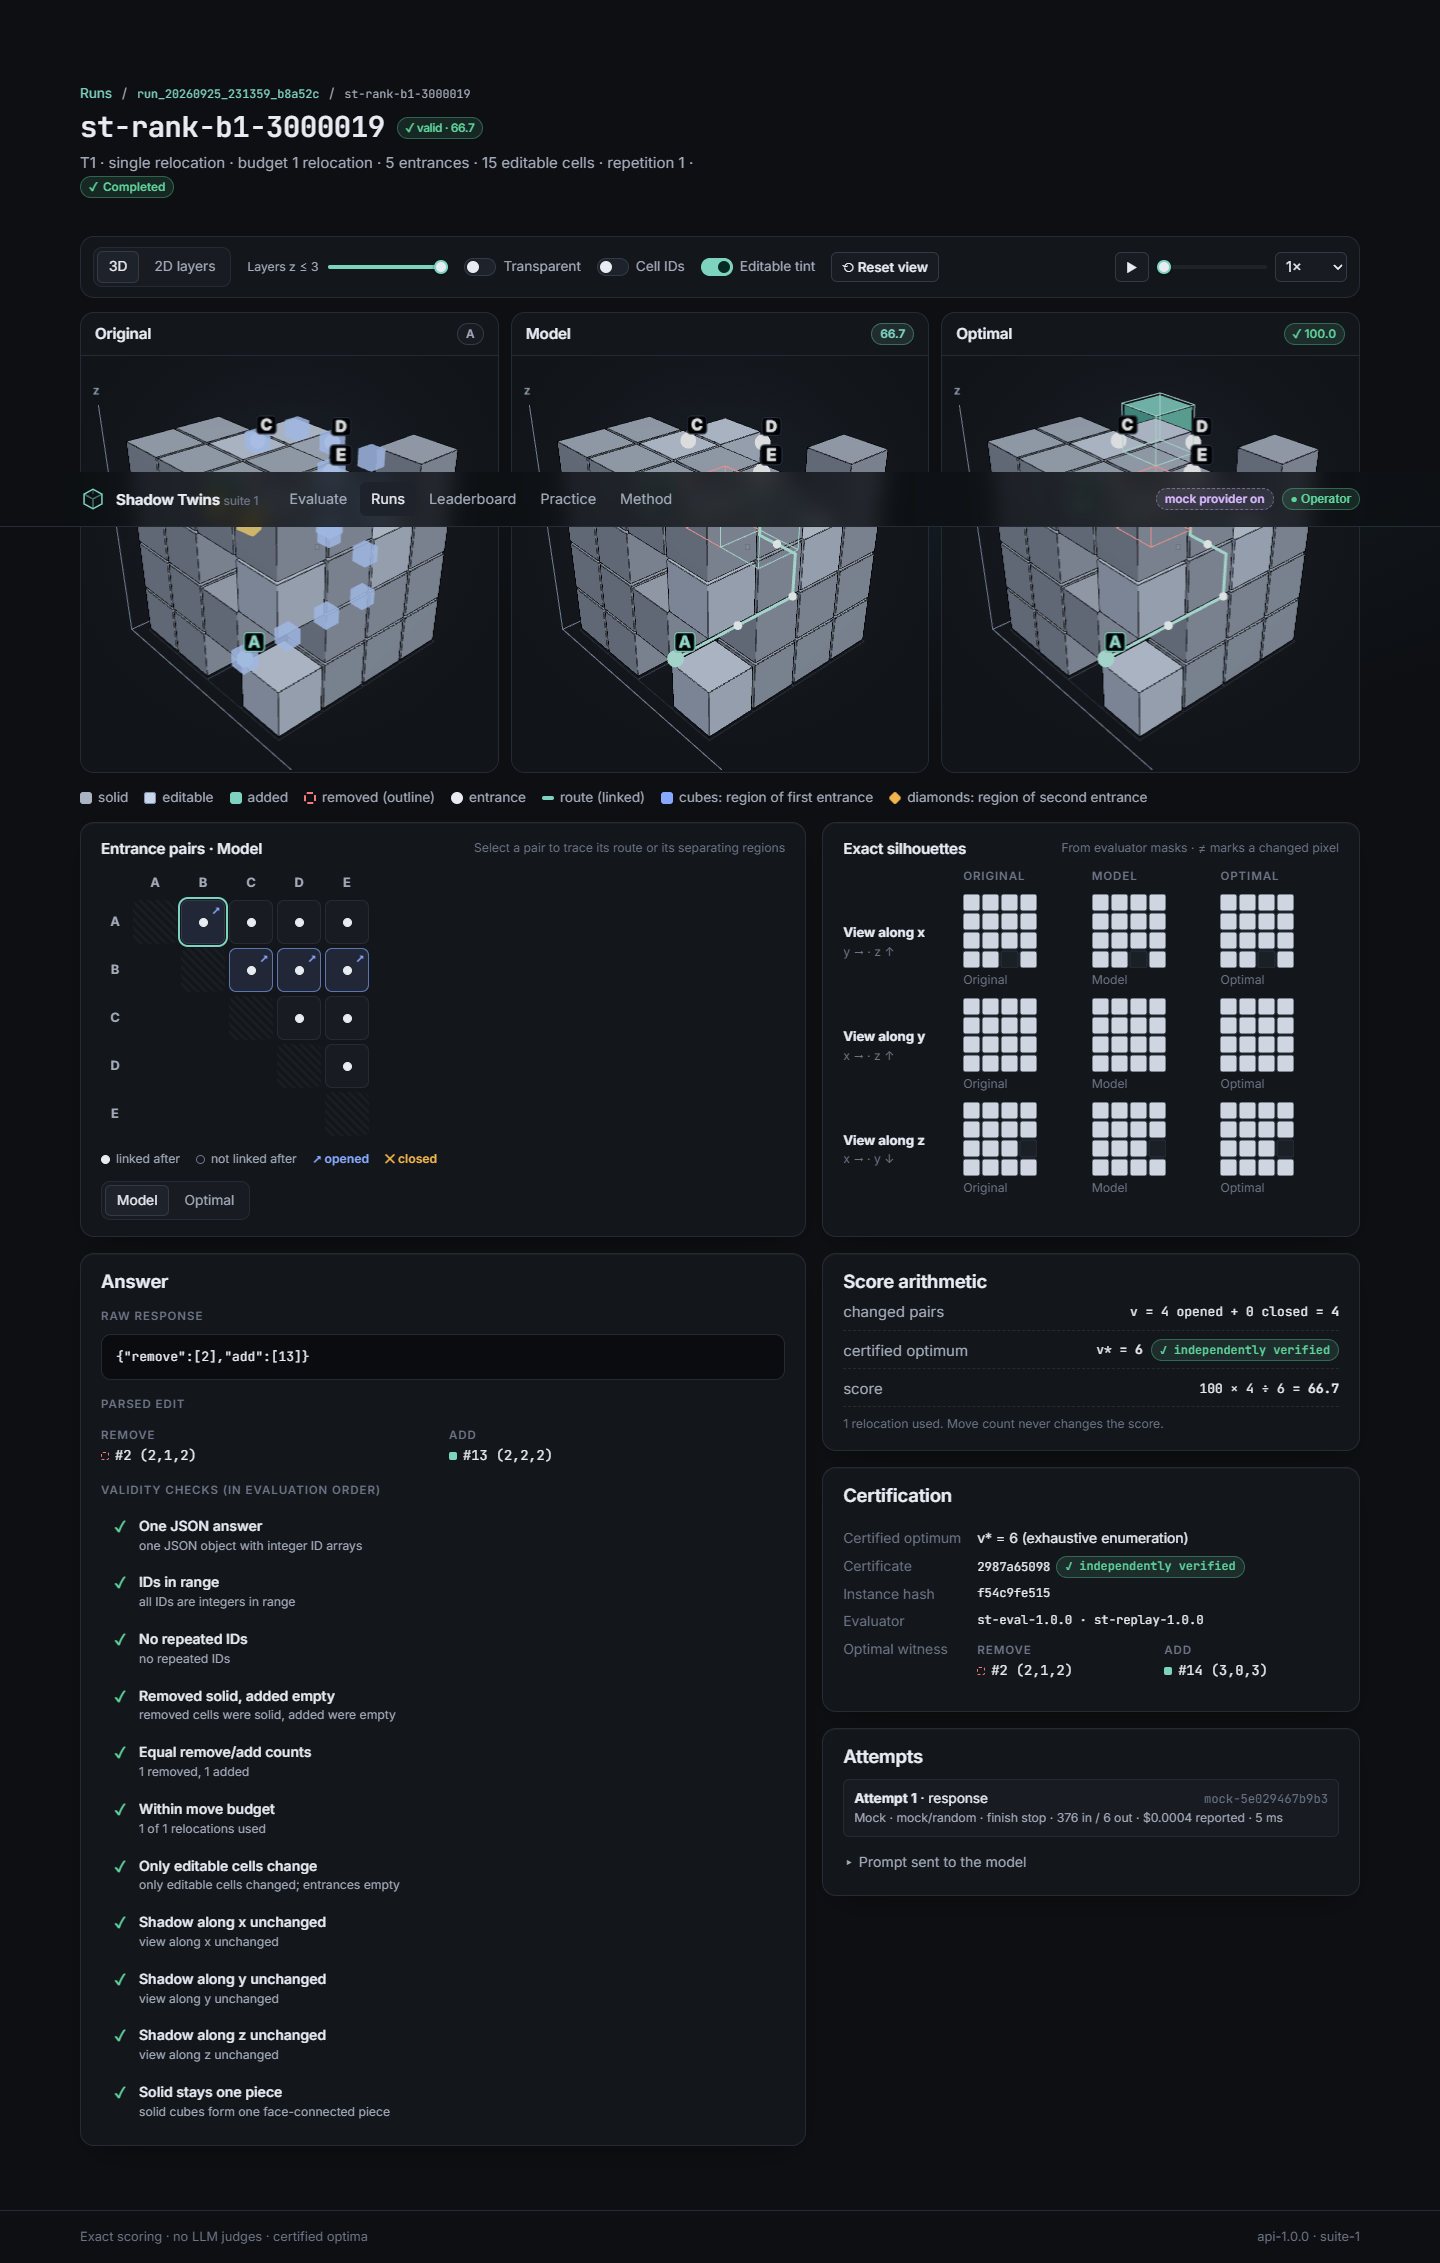
Same shadows. Different structure.
A spatial benchmark with exact scoring. Inspect the original object, a model’s answer, and the certified optimum side by side.
Every action needs an evidence trail.
An operations agent that investigates shipment exceptions, grounds its findings, and keeps a supervisor in control.
Open the model. Understand the bytes.
A Rust CLI for inspecting weights, finding unhealthy tensors, and comparing checkpoints, from hand-written binary parsers.
What does a model leave behind?
Two prespecified studies of normalization and forgetting after a training-domain switch. No predicted excess forgetting established.
Memory, competition, and life at the water’s edge.
A browser-based artificial-life lab exploring foraging, spatial memory, and resource competition, with a 3D ecosystem you can inspect creature by creature.
No projects match. Try another search or category.
Ideas worth testing. Each proposal starts with a question and ends with a way to measure progress.
Measure the tradeoff between useful action and unsupported confidence.
Extend OpsPilot with controlled missing, stale, and contradictory evidence. Compare always-answer, rule-based abstention, and confidence-threshold policies on the same reviewed cases.
Report unsupported-claim rate, useful completion rate, escalation frequency, and latency across evidence conditions. Publish the cases and failure taxonomy alongside the curves.
Does a model’s spatial reasoning survive a change in representation?
Build on Shadow Twins’ planned symmetry comparisons. Rotate equivalent objects, permute coordinate descriptions, and compare answers while holding the certified optimum fixed.
Measure paired score differences and invalid-answer categories. Keep variants clustered with the original instance; distinguish representation sensitivity from task difficulty.
Explore whether early diagnostics anticipate persistent deterioration.
Following the completed screening studies, design a separate exploratory study of checkpoint-level loss and representation diagnostics around a domain switch. Keep the existing pilot protocol unchanged.
Test prespecified early-warning signals on held-out runs. Compare against simple loss-based baselines and report false alarms as well as detection lead time.
I’m Daniel Shdeed, a Full Stack Engineer building toward AI engineering through hands-on systems work and independent study.
I’m drawn to the space between a model that produces an answer and a system that deserves to be trusted. The data path. The failure mode. The experiment that challenges the assumption.
Interfaces, typed APIs, workers, and the infrastructure that connects them.
Exact scoring, paired comparisons, reproducible runs, and honest limits.
Look inside the model. Follow the evidence. Make the next experiment better.
AI engineering. Thoughtful systems.
Research-minded teams.